
Prompt Engineering…
During my Prompt Engineering internship at Valentius Kryptix, I learned how to design effective prompts to guide Large Language Models (LLMs) to generate accurate, relevant, and structured responses. The task focused on understanding how the wording, context, instructions, and examples provided in a prompt influence the model’s output. I explored different prompting techniques and compared their effectiveness across multiple inputs, evaluating the quality and consistency of the responses. Our target users are students who want to pursue internships and face difficulties while applying or selecting from internships & job opportunities. Also it helps students complete their tasks.
Key concepts covered:
- Zero-shot prompting: Giving instructions without examples.
- Few-shot prompting: Providing examples to guide the model’s responses.
- Chain-of-thought prompting: Encouraging structured, step-by-step problem-solving.
- Structured output prompting: Generating information in formats such as JSON for easier processing.
- Prompt testing and evaluation: Testing different prompts, comparing outputs, and measuring response accuracy and consistency.
- Prompt optimization: Refining instructions and adding relevant context to improve results.
Overall, the task helped me understand how prompt engineering improves the reliability and usefulness of AI applications.
- Objective and model used
The following report evaluates three prompt engineering techniques: zero-shot versus few-shot prompting, step-by-step reasoning prompts, and structured JSON output. The experiments use Google AI Studio and Gemini 3.8 as it easily gives the necessary output from the given input.
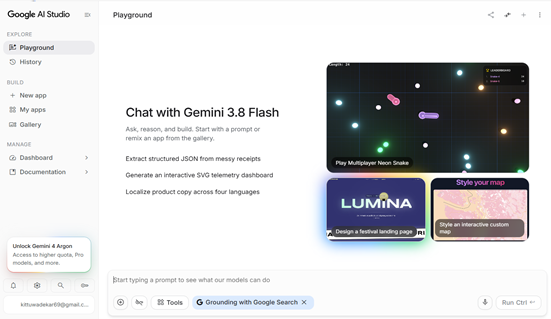
- Zero-shot vs. few-shot prompting
Task: Classify internship applicant messages into INTERESTED, NOT_INTERESTED, or NEEDS_FOLLOW_UP.
- Zero-shot — Test
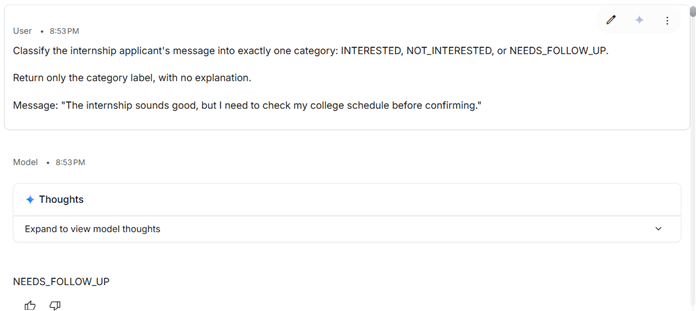
Few-shot output: NEEDS_FOLLOW_UP
Expected category: NEEDS_FOLLOW_UP
Correct: Yes
- Few-shot — Test 1
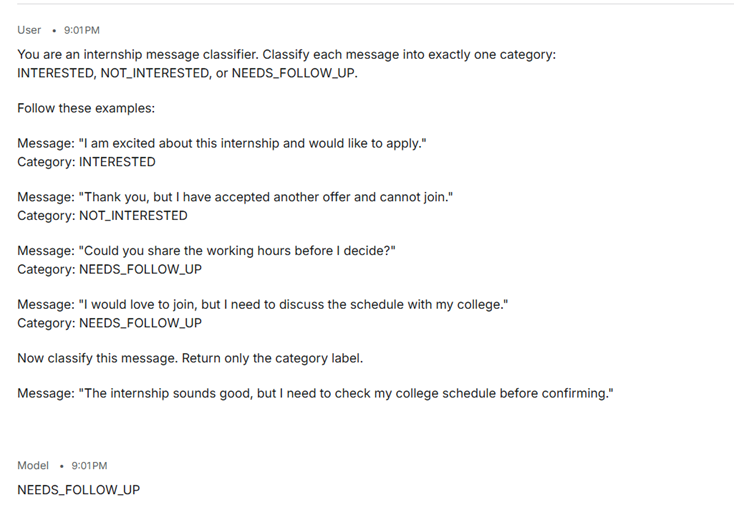
Few-shot output: NEEDS_FOLLOW_UP
Expected category: NEEDS_FOLLOW_UP
Correct: Yes
Analysis
Compare the two outputs for the same message. Each output is correct and have the clarity required for the expected classification.
- Step by Step Reasoning Prompting
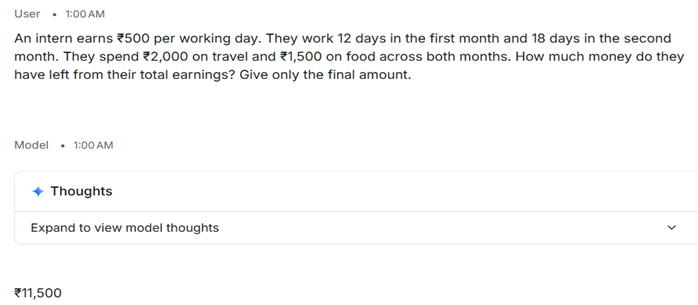
Test A: Direct prompt
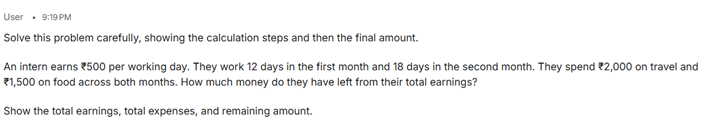
Test B : Step by Step Prompt
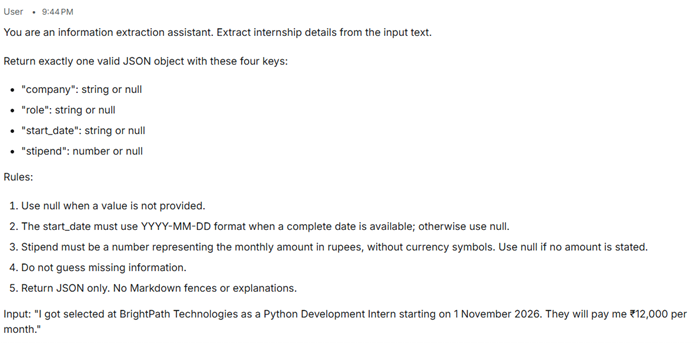
Correct answer for checking: ₹11,500.
Analysis
We have compared the final answers with the correct amount. Requesting intermediate calculations did made the result easier to verify and improve accuracy as we implement step by step which helps us to understand what exactly the task is to be done. And if any error or defect occurs, we can correct it immediately without much loss. The calculated output is equal to the expected output.
- Structured JSON output
Schema: company (string or null), role (string or null), start_date (string or null), stipend (number or null).
- Test 1
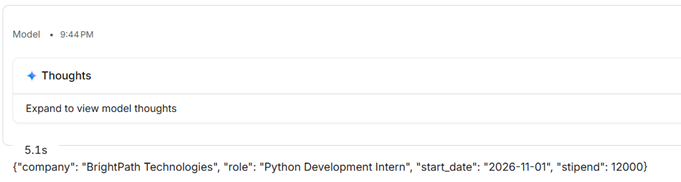
- Valid JSON: Yes
- All required keys present: Yes
- Values correct: Yes
- Test 2
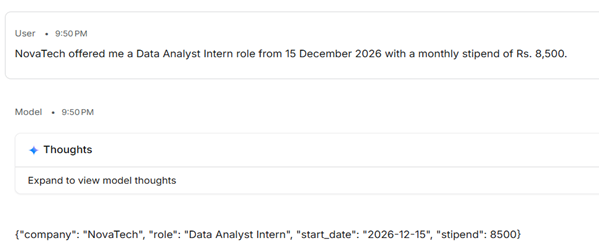
- Valid JSON: Yes
- All required keys present: Yes
- Values correct: Yes
- Test 3
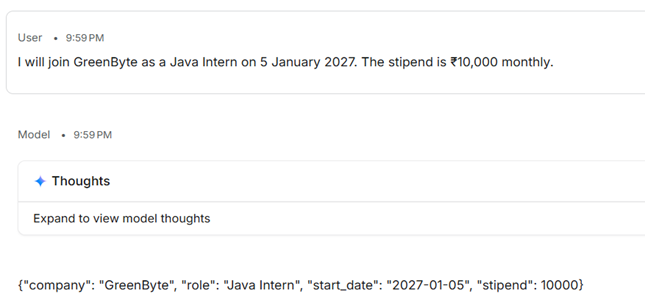
- Valid JSON: Yes
- All required keys present: Yes
- Values correct: Yes
- Test 4
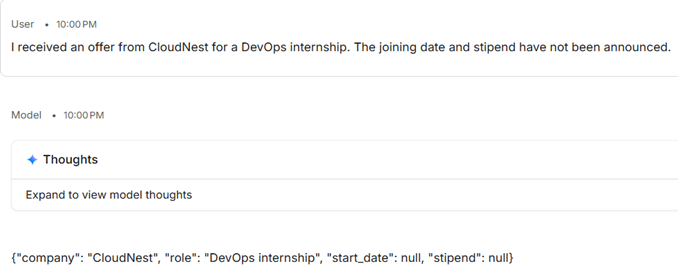
- Valid JSON: Yes
- All required keys present: Yes
- Values correct: Yes
- Test 5
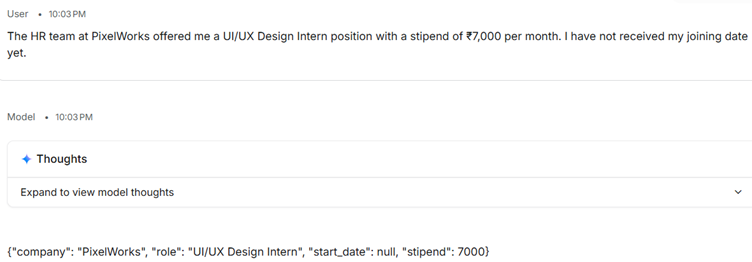
- Valid JSON: Yes
- All required keys present: Yes
- Values correct: Yes
Analysis
Explicitly listing keys,defining data types, requiring null for missing information, and requesting JSON does affect reliability as more accurately the SQL Queries are executed. Hardly failures and inconsistencies were seen.
- Results and conclusion
Success Rate:
Successful tests: [actual count]/5.
Success rate = successful tests ÷ 5 × 100 = [actual percentage]%.
In our case; all 5 cases have been executed successfully.
Hence, success rate= 5/5 * 100 = 1 * 100 = 100% .
| Validation | Result |
| Valid JSON syntax | ✅ Pass |
| All 4 required keys present | ✅ Pass |
| Missing date represented as null | ✅ Pass |
| Missing stipend represented as null | ✅ Pass |
| Role matches your defined schema exactly | ✅ Pass |
Conclusion
5. Conclusion
These experiments demonstrated that prompt engineering can improve the clarity, consistency, and reliability of LLM responses. In my observation, providing two to three relevant examples can often be enough to guide a model toward the expected output, although the ideal number depends on the task and its complexity. Step-by-step explanations can make multi-step calculations and reasoning easier to verify, particularly in sensitive or high-stakes contexts. However, the results must still be independently checked, as a detailed explanation does not guarantee correctness.
Explicit schemas improve structured output by defining the required keys, data types, formatting rules, and how missing information should be represented. This makes the output easier to validate and use in applications. The experiments also had limitations: only a small number of test cases were used, and results may vary depending on the model, wording of the prompt, and amount of context provided. When sufficient context is missing or instructions are ambiguous, the model may produce incomplete, inconsistent, or incorrect responses. Therefore, reliable prompt engineering requires clear instructions, appropriate examples, validation, and testing across a wider range of inputs.
Reproducibility note: The prompts and outputs in this report are the actual recorded results from the experiments.
My socials: Anjali Wadekar | LinkedIn

Leave a Reply
You must be logged in to post a comment.