
From Chatbot to Agent: What I Learned Building ResearchPilot
During my internship at Valentius Kryptix, my final milestone was to build an agentic AI workflow: a system that doesn’t just generate text, but decides which tools to use and acts on its own. I built ResearchPilot. The biggest lesson was that making an agent work once is easy. Making it reliable is the real challenge.
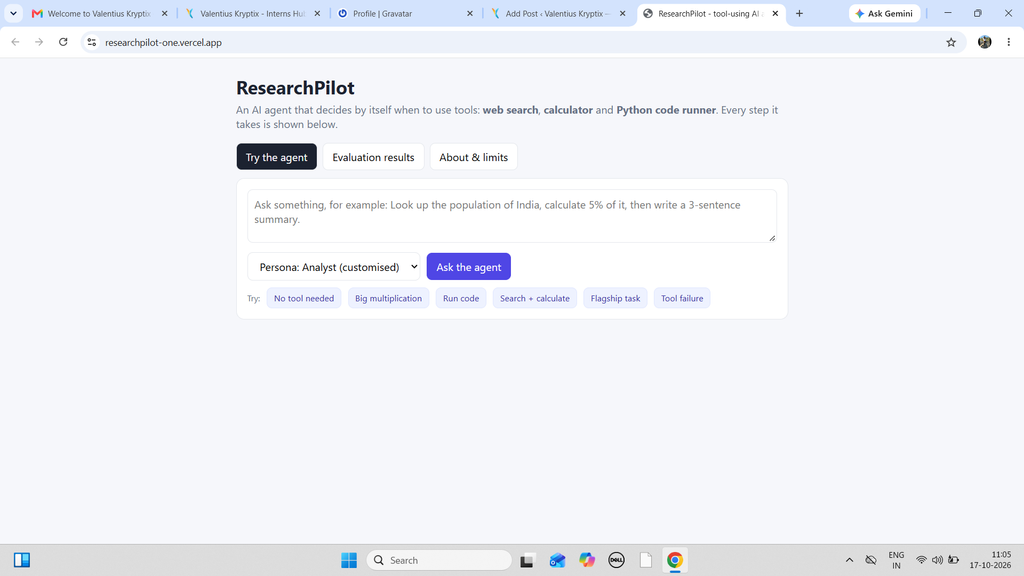
Here is the live app. You type a question, pick a persona, and the agent decides which tools to use.
What I built
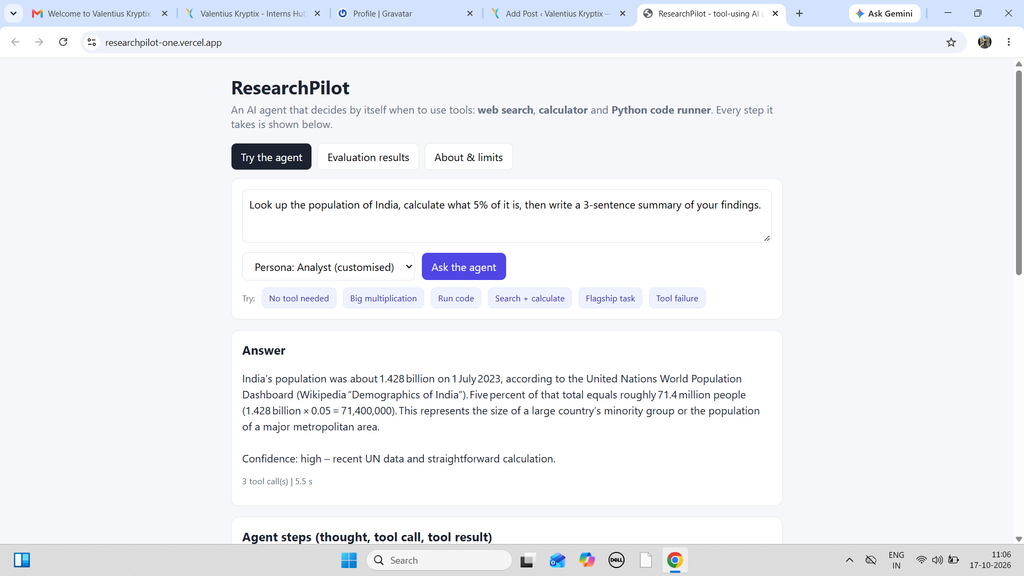
ResearchPilot has three tools: web search for live information, a calculator for exact arithmetic, and a Python code runner. These are things a language model can’t do reliably by itself. The agent decides when a tool is needed. Ask for the capital of France and it answers directly. Ask it to multiply two 11-digit numbers and it calls the calculator. Ask it to “look up the population of Pune, calculate 10% of it and add 100” and it chains a search with a calculation. Every step (thought, tool call, tool result) is shown on the page, so you can see why it acted. I used Python, LangChain, FastAPI, an open-source model (gpt-oss-120b) through Groq’s free API, and deployed it on Vercel.
Testing it properly
“It seems to work” isn’t good enough. I wrote 25 test cases covering no-tool questions, calculations, code, search, multi-step tasks and failure handling, each with a clear pass rule. My first run passed 22 of 25 (88%). The three failures taught me the most: the model sent a broken tool call, one correct answer failed only because my test insisted on the calculator, and the judge couldn’t verify a quoted price.
Here is a multi-step task. The agent first searches the web for the height of Mount Everest, then passes that number to the calculator. Every step is shown, so you can see why it acted.
What broke after deployment
Real use exposed problems my tests missed. The model sometimes sent malformed tool calls, returned empty answers, ran past Vercel’s time limit, and hit the free plan’s token-per-minute limit. I fixed these one by one with automatic retries, a nudge when the model stops without answering, a 40-second time budget, shorter search results, and a backup model for rate limits. Because anyone can use the live link, I also restricted the code runner to safe operations.
Customisation
I gave the agent a specialised “Analyst” persona that leads with the answer, names its sources and ends every reply with a confidence line. I measured it too: the format was followed on 88% of answers.
Try it live: https://researchpilot-one.vercel.app/

Leave a Reply
You must be logged in to post a comment.