
Introduction
Artificial Intelligence is becoming a part of our everyday lives. From answering questions to analysing documents, AI tools are helping people work smarter and faster. But there is one important question we should always ask: How reliable are the answers generated by AI?
Building an AI application is only one part of the process. We also need to test its responses, understand its limitations, and find ways to make it better.
During my internship at Valentius Kryptix, I worked on an AI Evaluation task focused on a Retrieval-Augmented Generation (RAG) Document Q&A project. This experience gave me an opportunity to explore how AI answers can be evaluated using measurable criteria rather than simply assuming that a response is correct.
What Does AI Evaluation Mean?
AI evaluation is the process of checking how well an AI system performs. It helps us understand whether a system provides useful, relevant, consistent, and reliable responses.
For example, an AI chatbot might generate an answer that sounds convincing but contains information that cannot be found in the supplied documents. Without proper evaluation, such problems can easily go unnoticed.
That is why evaluation is important. It helps developers identify weaknesses, measure performance, and make informed improvements.
Exploring RAG: Connecting AI with Documents
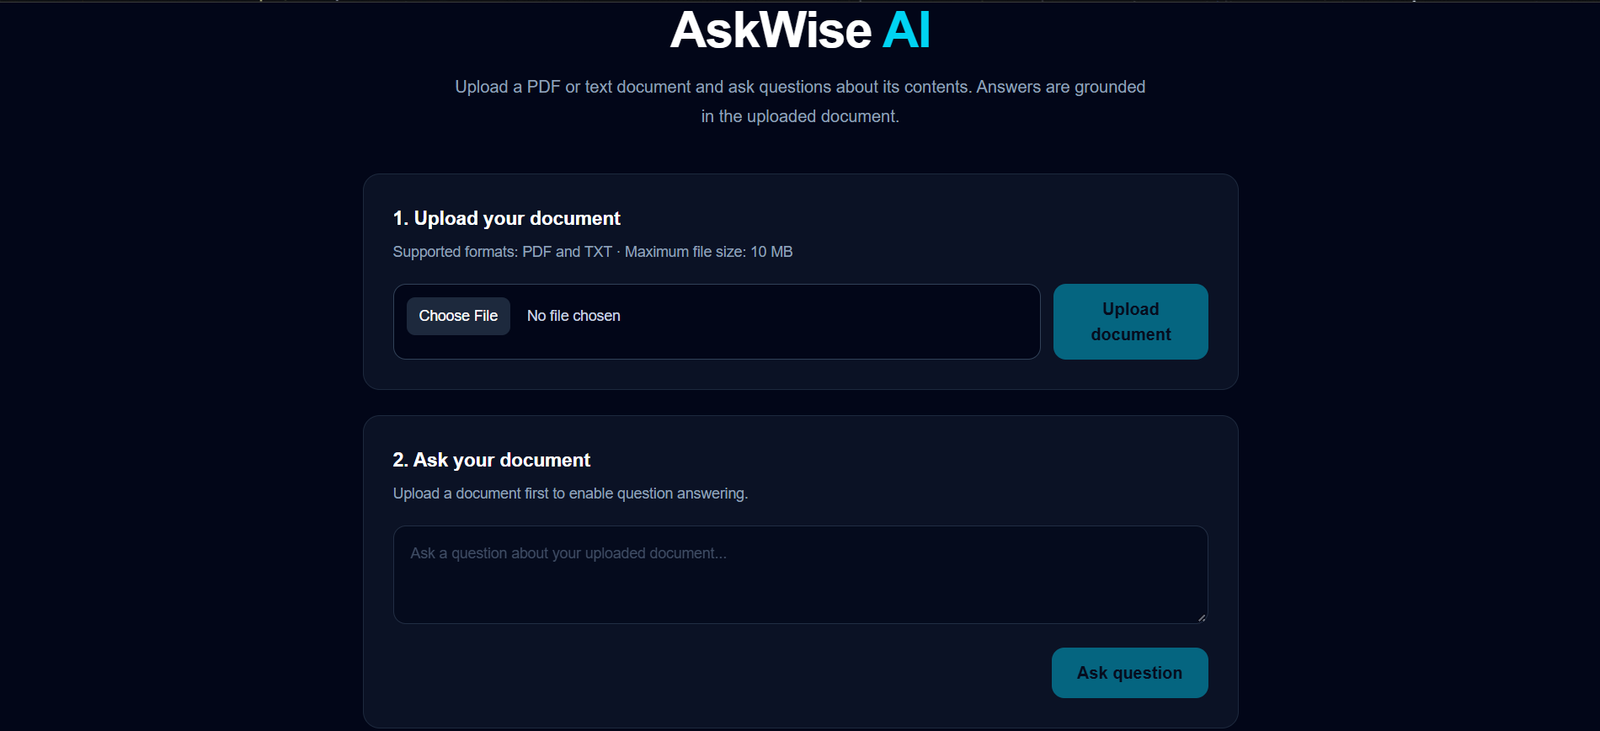
For this project, I worked with a RAG-based question-answering system.
RAG stands for Retrieval-Augmented Generation. In simple terms, it allows an AI application to search through a collection of documents and use relevant information from those documents to answer a question.
Here is how my project works:
- Document ingestion: The application reads supported Markdown, text, and text-based PDF files.
- Text chunking: Documents are divided into smaller sections so relevant information can be retrieved more efficiently.
- Embedding generation: Sentence Transformers converts text into numerical representations called embeddings.
- Information retrieval: ChromaDB stores the embeddings and helps retrieve relevant passages when a user asks a question.
- Answer generation: Groq provides the language model used to generate an answer based on the retrieved information.
One useful feature is that the application can display the retrieved passages, allowing users to inspect the information behind an answer.
How I Evaluated the AI System
To understand how well the system performed, I created a test dataset containing 20 test cases covering Python fundamentals, data structures, file handling, and retrieval-related questions.
I then used a custom LLM-as-a-judge evaluation approach with Groq. In this approach, a language model helps assess responses against defined criteria.
I focused on three main evaluation metrics.
1. Faithfulness — Is the Answer Supported?
Faithfulness checks whether the generated answer is supported by the retrieved context. A reliable response should avoid making unsupported claims or introducing information that the supplied evidence does not establish.
2. Answer Relevancy — Does It Answer the Question?
An answer may contain useful information but still miss the user’s actual question. Answer relevancy helps estimate how directly the response addresses what was asked.
3. Context Precision — Did the System Retrieve Useful Information?
Context precision measures how many of the retrieved passages were judged relevant to the question. This metric helped me identify an area where the retrieval process could be improved.
I also measured the expected source hit rate to understand how often the expected source was retrieved among the successfully evaluated cases.
Evaluation Results: What Did I Discover?
The evaluation produced the following results:
| Evaluation Metric | Result |
|---|---|
| Total test cases | 20 |
| Successfully evaluated | 19 |
| Failed cases | 1 |
| Average faithfulness | 98.26% |
| Average answer relevancy | 88.21% |
| Average context precision | 31.58% |
| Expected source hit rate | 84.21% |
Note: The metric averages were calculated over the 19 successfully evaluated cases.
The results revealed some interesting insights.
The system received a high estimated faithfulness score of 98.26%, while answer relevancy reached 88.21%. These results suggest that the evaluated answers were generally supported by their retrieved context and addressed the questions reasonably well.
However, context precision was only 31.58%. This highlighted an important challenge: the system could retrieve passages that were not sufficiently relevant to the question.
One test case could not be evaluated because of an API connection error. A subsequent retry was blocked by Groq’s token-per-day rate limit, so the failed case was excluded from the metric averages.
These results were produced using my custom LLM-as-a-judge evaluator. They are estimates, not official RAGAS benchmark scores, and should be interpreted with that limitation in mind.
My Biggest Learnings
This project taught me several practical lessons about building and evaluating AI applications.
- A good answer starts with good retrieval. Even a capable language model can struggle when the information provided to it is irrelevant or incomplete.
- One metric is never enough. Faithfulness, answer relevancy, and context precision help evaluate different aspects of a RAG system.
- Transparency builds trust. Showing retrieved passages makes it easier to inspect the evidence used to generate an answer.
- Failures are part of the learning process. Recording API errors and incomplete evaluations helps us understand the limitations of a system instead of hiding them.
Most importantly, I learned that evaluating AI is not just about getting a high score. It is about understanding what works, discovering what does not, and identifying practical ways to improve the system.
Challenges and Future Improvements
This project is an educational prototype with a relatively small document collection. The custom evaluator also depends on a language model, which means its judgements may vary.
There are several ways I would like to improve the system in the future:
- Expand the evaluation dataset with more diverse questions.
- Experiment with different text-chunking strategies.
- Fine-tune retrieval settings to reduce irrelevant passages.
- Compare different embedding models and retrieval configurations.
- Repeat evaluations under consistent conditions to improve comparability.
These improvements could help make the system more reliable and provide a clearer picture of its performance.
Conclusion
Working on this AI Evaluation task was a valuable learning experience during my internship at Valentius Kryptix. It helped me connect concepts such as Python, vector databases, document retrieval, and language models with the practical challenge of measuring AI reliability.
The evaluation showed promising faithfulness and answer relevancy estimates, while also revealing that retrieval precision needs more attention.
This experience reinforced an important lesson for me: building AI is important, but testing it carefully is what helps us understand its real strengths and limitations.
I look forward to applying these learnings to more AI and Data Science projects and continuing to grow as a developer.
Technologies Used: Python, ChromaDB, Sentence Transformers, Groq, RAG, and LLM-as-a-judge evaluation.
Explore the Project on GitHub:
https://github.com/pavanbhusare19/rag-document-qa
Thank you to Valentius Kryptix for providing this learning opportunity.
#ArtificialIntelligence #DataScience #Python #RAG #MachineLearning #ValentiusKryptix #AIEvaluation

Leave a Reply
You must be logged in to post a comment.