
Large Language Models are remarkably good at answering questions, but they have an important limitation: they can only answer based on the information available to them at inference time.
If the information is specific to a collection of documents, internal files, research papers, notes, or company data, simply asking an LLM a question may not be enough. This is where Retrieval-Augmented Generation (RAG) becomes useful.
So as a project, I built a basic RAG chatbot to address this problem. I made the entire pipeline of the project run using local models. Never used any LLM API calls and cloud servies in the project.
The system uses:
- A local embedding model for semantic retrieval
- BM25 for keyword-based retrieval
- A local reranker for improving the retrieved results
- A local chat model for generating the final answer
This post walks through the pipleine of the project.
First of all “What is RAG”
RAG stands for Retrieval Augmented Generation. It differs from the conventional LLM workflow by Retrieving from the context provided to it apart from what the LLM knowledge already had. Instead of asking the LLM to answer purely from its internal knowledge, we first retrieve from our own documents and provide information to the model.
Now the goal of my project was simple. It was to show that if provided LLM the context, It can improve its answer quality. The entire workflow is described below:
I provided the model the documents as context. These documents are processed, chunking(breaking the document into multiple parts) happens. These chunked portions are embedded using local embedding model and stored into chromaDB vector database locally. Now when the question is asked, It is first converted to vector embeddings and chromDB performs similarity search of query vector with document chunks to find the most relevant context. Along with similarity search, I also perform BM25 indexing(keyword-matching) to make retrieval more precise. Then top chunks are send to reranker(cross-encoders) to get the relevant context. Which is then send to local chat model to generate the final answer.
Why did I use “Local Models” ?
Main reason was privacy protection. No document is going on internet and cloud services, so no information is getting leaked out of the computer.
Once the models are available locally, there is no per-request API cost for embeddings, reranking, or generation.
But One downside of using local models is that It can be very slow in running the pipeline.
Testing the system
After building the whole pipeline, I tested my model if it is Retrieving better answer. Instead of only looking at whether the chatbot produced an answer, I wanted to compare what happened when the same question was asked with and without retrieval context.
The question I used was:
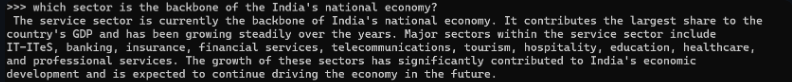
“Which sector is the backbone of the backbone of India’s national economy?”
The answer to the question provided by the chat model without providing the context is following:
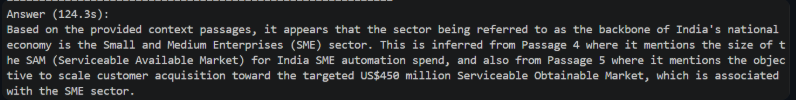
Then when I asked the RAG model the same question it answered the following:
Now i will give what was written in the context (actual):
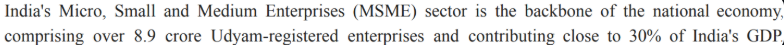
What This Experiment Demonstrates
This simple experiment highlights one of the core ideas behind RAG.
A language model does not necessarily need to have every piece of information encoded in its parameters.
Instead, we can provide relevant information at inference time.
What I Learned From Building It
There are several independent components that determine the quality of the final response.
The retrieval strategy matters.
The quality of the embeddings matters.
The chunking strategy matters.
The reranker matters.
The quality of the retrieved context matters.
And finally, the generation model still matters.
I am still learning how can I improve this model at every aspect.

Leave a Reply
You must be logged in to post a comment.